
Spark X2.6 4B
XHToken/Spark-X2.6-4B-GGUF
LocalBF169.4 GB at 32K136 tok/s on RTX 5090605K context
15
17 of 153 test cases fully passed
Watch the test
Spark X2.6 4B Local Test | Beats Qwen3.5 4B? | Agentic Work, Coding & RAG Test | 16GB Local AI Setup
Watch on YouTubeWhat it built
What it wrote for showcase prompts, running live in your browser.
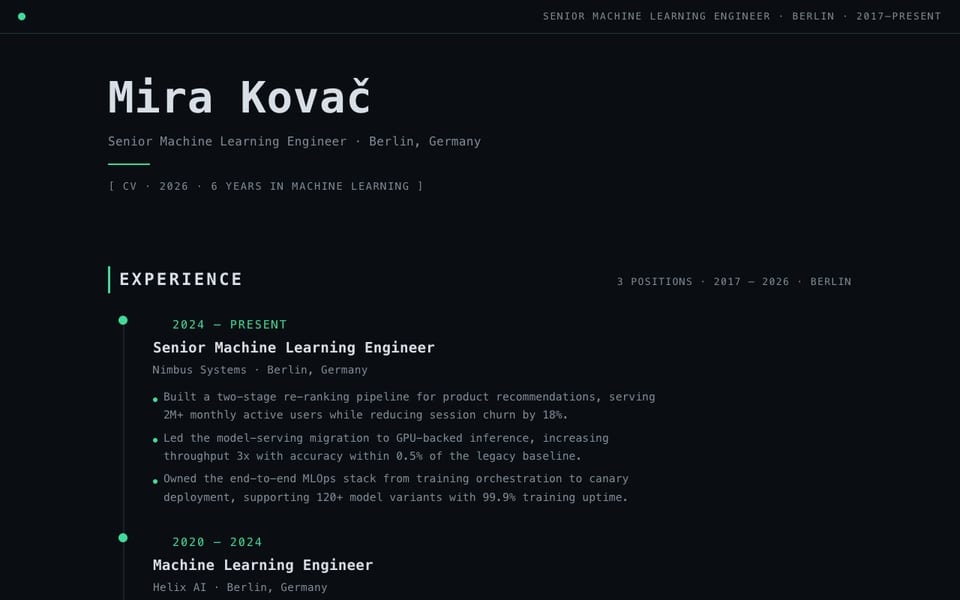
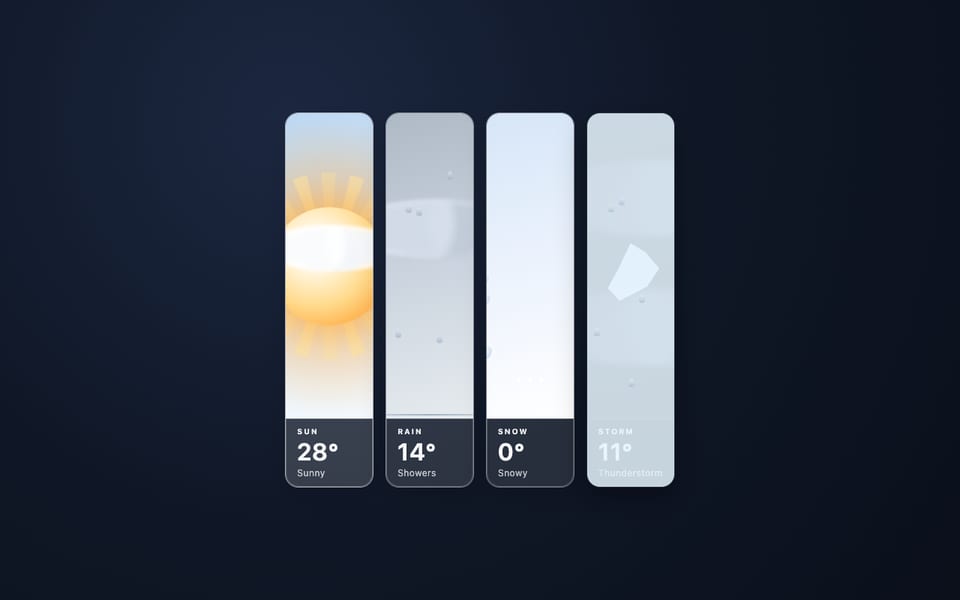
Scores by task
Scores give partial credit. Passed counts fully correct answers only. Select a task to read its test cases.
Run it yourself
The exact build behind this score, and the command that serves it.
- Local
- llama.cpp
- BF16
- -ngl -1 --temp 1.0 --top-p 0.95 --top-k 0 --reasoning on
- 605K
- 9.4 GB at 32K
- RTX 5090, 32 GB
- 136 tok/s
- $1.61est.
- $0.011est.
- 1m 3s
- 2026-10-21
llama.cpp
llama-server -hf XHToken/Spark-X2.6-4B-GGUF:BF16 --port 9931 -c 619520 -ngl -1 --temp 1.0 --top-p 0.95 --top-k 0 --reasoning onPulls the GGUF from Hugging Face and serves an OpenAI-compatible endpoint on port 9931.
Memory it needs
7.7 GB of weights, 492 MB of runtime, and 39 MB per 1K tokens of context.
| Context | Memory | Smallest Mac | Smallest GPU |
|---|---|---|---|
| 8K | 8.5 GB | 16 GB | 12 GB |
| 32K | 9.4 GB | 16 GB | 12 GB |
| 128K | 13.0 GB | 24 GB | 16 GB |
| 1M | 47.1 GB | 96 GB | 80 GB |
One email when a new model lands on the board or in the showcase. Unsubscribe anytime.